1 - Deploy Hermes Agent in a Proxmox LXC with Community Scripts
Deploy Hermes Agent in a Proxmox LXC using the Community Scripts installer, then configure and verify a minimal working setup.
A small, repeatable Hermes Agent deployment for a Proxmox VE container.
Community-maintained installer
This installer is maintained by the Community Scripts project, not by Nous Research. It downloads and runs code from external sources. Review the current script and use it only on a Proxmox host you administer.
Before you start
Have the following ready:
A Proxmox VE host with capacity for a new LXC container.
A current backup or recovery plan for the host and any affected storage.
Outbound HTTPS access from the host and the new container.
A model-provider account or an approved OpenAI-compatible endpoint. Complete provider authentication only in Hermes’ interactive setup; do not put credentials in shell history or documentation.
The Community Scripts page currently lists a Debian 13 profile with 2 vCPUs, 4 GiB of RAM, and 20 GiB of disk. Treat these as installer defaults, not sizing guidance. Select the advanced installer flow when your workload needs different limits.
Create the container
In the Proxmox VE shell, review the installer source linked from the Community Scripts page.
Follow the prompts to create the LXC, then start it.
The script creates a dedicated hermes service user. The container is a useful isolation boundary, but Hermes can execute commands inside it. Do not treat it as safe to expose directly to an untrusted network.
Configure Hermes
Open the LXC console and switch to the service user:
su - hermes
hermes setup
Use the setup wizard to select and authenticate a provider. Configure one working model first; defer gateways, messaging integrations, and other automation until a normal chat succeeds.
Verify the deployment
Still as the hermes user, run:
whoami
hermes --version
hermes doctor
hermes chat -q "Reply with exactly: Hermes is ready."
Expected results:
whoami returns hermes.
hermes --version prints an installed version.
hermes doctor completes without a blocking configuration error.
The chat command receives the requested response from the configured model.
If the chat test fails, run hermes model to review the selected provider and model, then repeat the test. Do not add a dashboard, gateway, or messaging channel until this baseline works.
Access the dashboard safely
The Community Scripts page documents a dashboard on the container’s loopback interface. Reach it through an SSH tunnel instead of publishing the dashboard port:
Open http://localhost:9119 on the machine running the tunnel. Replace both placeholders with values appropriate to your environment. Keep the dashboard private unless you have separately designed and reviewed its authentication and network controls.
Troubleshooting
Symptom
Check
hermes: command not found
Start a new shell after su - hermes, then confirm the installer completed successfully.
hermes doctor reports a provider or model problem
Re-run hermes setup or hermes model as the hermes user and complete the provider configuration.
The dashboard does not load through the tunnel
Confirm the tunnel remains open and verify the container is running before changing firewall or exposure settings.
2 - Self-Host Honcho on Kubernetes with LiteLLM, Redis, and GitHub Copilot
Deploy self-hosted Honcho memory on Kubernetes and route embeddings, fast extraction, and deep reasoning through LiteLLM and GitHub Copilot.
A self-hosted memory service for Hermes, with LiteLLM as the model gateway and GitHub Copilot as an upstream provider.
Illustrative configuration only
Every hostname, namespace, IP address, image version, model name, key and resource value in this guide is an example. Do not paste it into a production cluster unchanged. Create your own secrets outside Git, verify the current upstream image and model names, and apply your own network, backup and update policies.
Architecture at a glance
The request path is deliberately split into specialised layers:
Hermes asks Honcho to search, retrieve, derive, or reason over long-term memory.
Honcho owns the memory domain: API/authentication, PostgreSQL + pgvector persistence, and background derivation.
LiteLLM is the only LLM-facing gateway. Honcho calls its OpenAI-compatible /v1 API using stable aliases rather than knowing provider-specific model IDs.
Redis is configured by LiteLLM as its shared proxy cache and coordination store — it is not a Honcho cache pod in this design.
GitHub Copilot or another upstream provider performs generation and embeddings.
That separation means an application such as Honcho does not need to be rewritten when the upstream provider, model, routing policy, key, quota, or cache policy changes.
Why put LiteLLM and Redis in the middle?
LiteLLM is the provider boundary
Honcho can use any OpenAI-compatible endpoint for generation and embeddings.[3] LiteLLM turns that into a single internal API and a small set of application-specific aliases:
Alias
Purpose
Example upstream model
Why it is separated
honcho-fast
Derivation, extraction, small summaries
Claude Haiku-class model
High-frequency work; optimize latency and cost
honcho-reasoning
Medium, high, and max-depth synthesis
Claude Sonnet-class model
Reserve deeper reasoning for the requests that justify it
honcho-embeddings
Vector representation for memory retrieval
text-embedding-3-small
Embeddings are a distinct workload and endpoint type
The aliases are the contract that Honcho depends on. LiteLLM maps that contract to an upstream provider and can centralise virtual keys, budgets, rate limits, fallbacks, logs, and routing. This also lets you replace a model without editing the Kubernetes deployment.
LiteLLM documents GitHub Copilot as an OAuth device-flow provider and supports both chat/reasoning calls and embeddings through the proxy.[2] Store the provider session in persistent storage owned by LiteLLM; do not expect an interactive OAuth session stored in a disposable container filesystem to survive a redeploy.
Redis is LiteLLM’s shared cache
In this pattern, Redis belongs to LiteLLM, not to Honcho. Honcho keeps durable memory in PostgreSQL + pgvector and sends every model/embedding request to LiteLLM. LiteLLM then uses Redis for its own proxy-wide state:
exact-match response cache, including repeated embedding calls;
shared cache invalidation across LiteLLM workers or replicas;
router, cooldown and rate-limit coordination;
shared state needed when the proxy scales beyond one process.
LiteLLM documents Redis as the sensible default once the proxy has more than one worker, because an in-memory cache is isolated per process while Redis is shared.[1] That gives one cache policy and one observation point for every Honcho request flowing through the gateway.
Configure both LiteLLM’s router state and its response cache to point to Redis. A representative configuration is:
Do not enable semantic response caching blindly for an agentic memory workload. Exact request caching is predictable; semantic caching can return a near-match for a different prompt, which is rarely what you want in a stateful tool workflow.[1]
Practical default
Run one Redis service for LiteLLM’s proxy cache and coordination. Keep the cache disposable: losing it should mean slower or more expensive requests, never lost Honcho memories. PostgreSQL + pgvector remains the durable store.
Why these three model roles?
A memory system does not need its most expensive model for every operation.
1. Fast model: extraction and summaries
Honcho’s routine work includes deriving facts from conversations, making compact summaries, and processing frequent small updates. A fast, capable model is a better fit than a heavyweight reasoning model here because the operations are numerous, bounded, and usually structured.
2. Reasoning model: dialectic synthesis
Use the deeper model only for medium/high/max reasoning: reconciling conflicting memories, answering a nuanced question about a person or project, or producing a careful synthesis. This is where a stronger model pays for itself, while reserving it avoids turning basic retrieval into an expensive operation.
3. Embedding model: retrieval, not prose
text-embedding-3-small creates vector representations used to retrieve related memory. It does not write responses for the user. Separating it into honcho-embeddings prevents an accidental configuration change from sending embedding calls to a chat model and makes its access policy, budget, and health checks explicit.
The key design principle is not the exact brand or model version. It is the workload-to-model mapping: cheap and fast for routine processing, strong reasoning only when requested, and a dedicated embedding endpoint for vector search.
Prerequisites
This guide assumes:
a working Kubernetes cluster (MicroK8s is used in the examples);
a private namespace such as privateapps;
an internal LiteLLM Proxy endpoint reachable from pods;
a LiteLLM virtual key restricted to the three honcho-* aliases;
persistent storage for PostgreSQL;
a trusted internal ingress or another controlled way to reach Honcho;
backups for PostgreSQL before treating it as a source of valuable memory.
The examples intentionally use placeholder values such as LITELLM_PROXY_URL, example.internal, and CHANGE_ME. They contain no real credentials or addresses.
Part 1 — Configure LiteLLM
1. Persist GitHub Copilot OAuth state
GitHub Copilot authentication uses OAuth device flow. The first request requires a human to open the verification URL and enter the device code; LiteLLM then stores the credentials for later requests.[2]
For a containerised LiteLLM proxy, mount a persistent volume for the token directory. The path below is illustrative:
# docker-compose.yaml or an equivalent container deployment — example onlyservices:litellm:image:ghcr.io/berriai/litellm:PINNED_VERSIONenvironment:GITHUB_COPILOT_TOKEN_DIR:/container_data/litellm/github_copilotvolumes:- /container-data/litellm/github_copilot:/container_data/litellm/github_copilot
Do not put OAuth tokens in Kubernetes manifests
Use the provider’s supported token storage and protect the host volume. Never copy OAuth access tokens into a ConfigMap, a Git repository, screenshots, or documentation.
2. Create stable model aliases
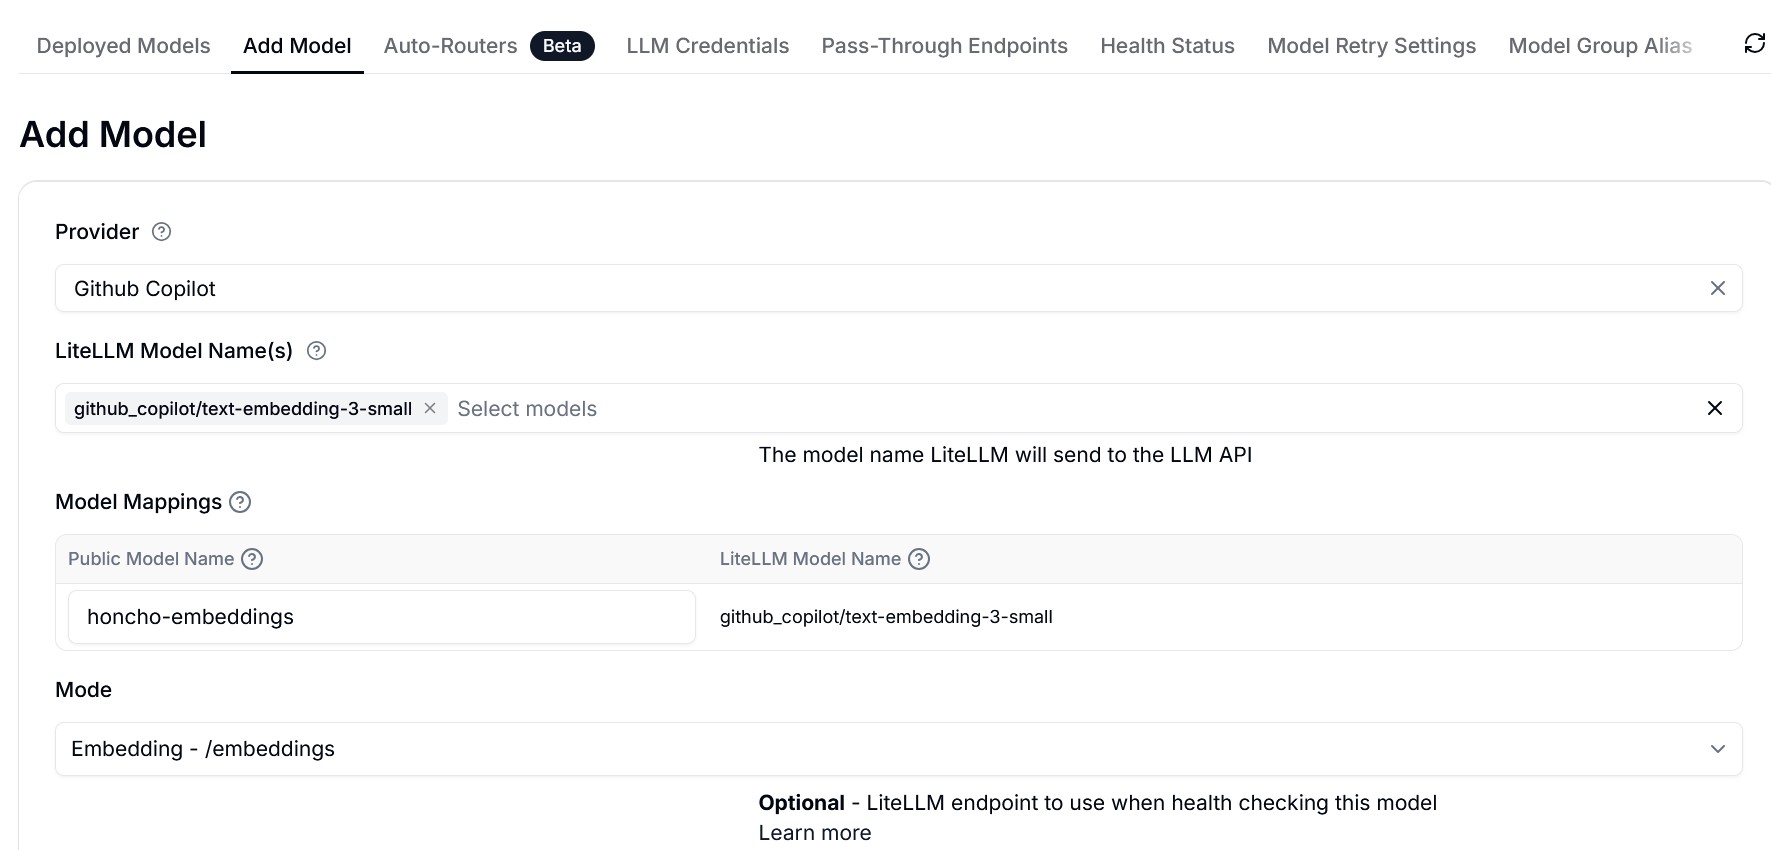
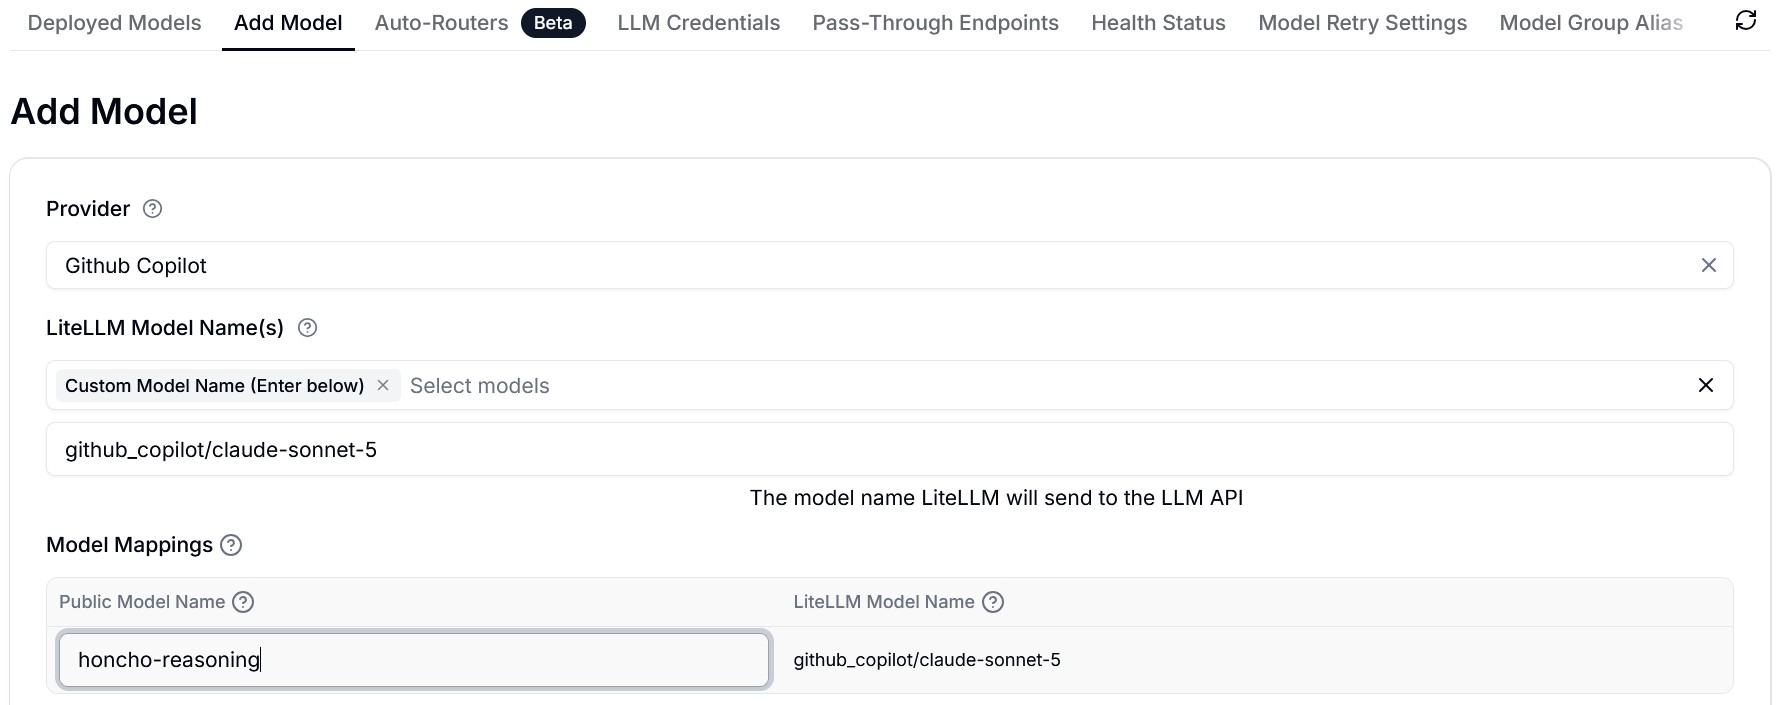
Create three models in the LiteLLM Admin UI, or declare equivalent aliases in its configuration. The upstream names below are examples: select the models available to your GitHub Copilot subscription and LiteLLM version.
LiteLLM’s GitHub Copilot provider documentation shows the same pattern: give the proxy a model alias, set model_info.mode: embedding for an embedding model, and map it to the GitHub Copilot provider model.[2]
Screenshot placeholders
Place the two screenshots provided with this article in this page bundle:
Create a virtual key for Honcho and restrict it to:
honcho-fast
honcho-reasoning
honcho-embeddings
Set an explicit budget and an expiry/review cadence appropriate to the environment. The point is not merely cost control: the allowlist prevents a compromised or misconfigured Honcho pod from invoking every model exposed by the shared gateway.
4. Verify LiteLLM before Kubernetes
From a trusted machine, test the aliases before deploying Honcho. Replace all placeholder values locally; do not save the key in shell history.
Expected outcome: both calls return HTTP 200, the chat request has a completion, and the embedding request contains a numeric vector. Test honcho-reasoning separately only when you need to validate its configured upstream model.
Part 2 — Deploy Honcho on Kubernetes
1. Keep secrets out of the manifest
The deployment needs database credentials, a JWT signing secret, and the LiteLLM virtual key. Create them as a Kubernetes Secret outside the YAML committed to documentation.
# Example only. Generate real high-entropy values locally.kubectl -n privateapps create secret generic honcho-runtime \
--from-literal=postgres-password='CHANGE_ME'\
--from-literal=db-connection-uri='postgresql+psycopg://honcho:CHANGE_ME@honcho-postgres:5432/honcho'\
--from-literal=auth-jwt-secret='CHANGE_ME_64_CHARACTERS_OR_MORE'\
--from-literal=litellm-api-key='REDACTED'
Use an external secrets manager or your existing secret workflow for a real deployment. The command is deliberately only a teaching example.
2. Example manifest
The following manifest is a compact representation of the Honcho side of the architecture. It creates:
PostgreSQL with the vector extension for durable memory and semantic retrieval;
one Honcho API deployment;
one background derivation worker;
ClusterIP services, so Honcho and PostgreSQL are not exposed outside the namespace.
Redis is configured and operated with the LiteLLM proxy, so it is intentionally absent from this Honcho manifest.
LLM_OPENAI_API_KEY is the LiteLLM virtual key, not the GitHub token.
...BASE_URL points at LiteLLM’s OpenAI-compatible /v1 endpoint.
honcho-fast, honcho-reasoning, and honcho-embeddings are aliases controlled by LiteLLM.
This manifest deliberately contains no CACHE_URL or Redis pod. LiteLLM owns the Redis-backed response cache and proxy coordination.
DREAM_ENABLED=false is an intentional cost-control choice for this pattern. Enable consolidation only after you understand its cadence and cost.
The worker repeats the same core model configuration as the API because it makes asynchronous derivation independently reproducible.
Example manifest, not a production baseline
A production deployment should additionally define NetworkPolicies, a real backup/restore test for PostgreSQL, image digests, pod security settings, anti-affinity/high availability where relevant, resource tuning from observed metrics, and a secrets integration appropriate to the cluster.
3. Apply and observe
Apply only after reviewing the rendered YAML and confirming that the Secret exists:
kubectl apply --dry-run=server -f honcho.example.yaml
kubectl apply -f honcho.example.yaml

kubectl -n privateapps rollout status deployment/honcho-postgres --timeout=180s
kubectl -n privateapps rollout status deployment/honcho-api --timeout=300s
kubectl -n privateapps rollout status deployment/honcho-deriver --timeout=300s

# LiteLLM and its Redis cache are operated and observed separately.
Verification checklist
Validate the deployment in layers rather than assuming a running pod proves the full path:
# 1. Kubernetes healthkubectl -n privateapps get deploy,pods,svc
# 2. Honcho API health from inside the clusterkubectl -n privateapps run honcho-healthcheck --rm -it \
--image=curlimages/curl --restart=Never -- \
curl --fail http://honcho:8000/health
# 3. Verify PostgreSQL extensionkubectl -n privateapps exec deploy/honcho-postgres -- \
psql -U honcho -d honcho -c '\\dx'# 4. Check the derivation worker without exposing secretskubectl -n privateapps logs deploy/honcho-deriver --tail=100
Then use a real Hermes memory operation and confirm all of the following:
Hermes can authenticate to Honcho;
a fast operation succeeds through honcho-fast;
an embedding request succeeds through honcho-embeddings;
a medium/high reasoning request reaches honcho-reasoning;
LiteLLM usage/logs show only the three permitted aliases;
no provider credential appears in logs, manifests, browser history, or Git.
Troubleshooting
Symptom
Likely cause
First check
Honcho API stays unready
PostgreSQL is not reachable or migrations fail
kubectl logs deploy/honcho-api and pg_isready
Deriver runs but creates no useful memory
Wrong model alias, missing structured-output support, or worker configuration mismatch
Worker logs; test honcho-fast directly through LiteLLM
Vector search fails
vector extension or embedding alias is missing
\\dx in PostgreSQL; LiteLLM /embeddings test
401/403 from LiteLLM
Virtual key is absent, invalid, expired, or model scope is too narrow
LiteLLM key policy and pod Secret reference
It worked until redeploy
OAuth token directory was ephemeral
Mount and protect a persistent LiteLLM token directory
Costs rise unexpectedly
Deep reasoning is being used for routine work or consolidation is too frequent
Alias-level usage; dialectic level; DREAM_ENABLED
LiteLLM cache misses after restart
Redis is unavailable, was restarted, or is misconfigured in the LiteLLM proxy
LiteLLM /cache/ping, Redis connection settings, and cache metrics; Honcho memory remains in PostgreSQL